Rapid-MLX
Run Codex, Claude Code, OpenCode, Pi, Hermes, Crush or Goose with a local model on Mac:rapid-mlx launch <agent>
Install on a stock Apple Silicon Mac with curl -fsSL https://rapidmlx.com/install.sh | bash, restart your terminal (or run export PATH="$HOME/.local/bin:$PATH"), then install your chosen coding agent and run, for example, rapid-mlx launch codex. Run the same command tomorrow; rapid-mlx launch codex --remove removes Rapid's private profile without changing your existing Codex settings. One-command guides for each agent. A first reply can take longer while a model downloads, loads, or processes the agent's opening prompt.
Rapid-MLX is an open-source (Apache 2.0) OpenAI- and Anthropic-compatible LLM inference server for Apple Silicon, built on MLX, focused on reliable tool calling for coding agents.
Up to 4× faster than Apple's MLX (mlx-lm), 1.5× on a typical task — same model, same weights.
Decode speed, Qwen3.5-9B 4-bit on a Mac mini M4 Pro, greedy decoding, both servers at their defaults — per-task results, method, and raw data.
Faster decode than oMLX and LM Studio on Qwen3.5-9B, Qwen3.8-27B, and Qwen3.6-35B
Measured speed on a Mac Studio M5 Max (36 GB) — Rapid-MLX 0.16.1 vs oMLX 0.7.0 and LM Studio, using the same base 4-bit weights for each model.
| Model | Metric | Rapid-MLX | oMLX | LM Studio |
|---|---|---|---|---|
| Qwen3.5-9B | Decode (tok/s) | 115.5 | 77.9 | 81.0 |
| Qwen3.5-9B | 4 streams (tok/s) | 248.2 | 224.6 | 230.0 |
| Qwen3.8-27B | Decode (tok/s) | 37.9 | 25.3 | 26.0 |
| Qwen3.8-27B | 4 streams (tok/s) | 82.8 | 75.3 | 69.7 |
| Qwen3.6-35B | Decode (tok/s) | 173.4 | 145.8 | 124.5 |
| Qwen3.6-35B | 4 streams (tok/s) | 293.9 | 281.9 | 265.6 |
| Qwen3.6-35B | 2K-prompt first token (s, lower is better) | 0.55 | 1.14 | 1.49 |
Single run per engine; default serving modes with Rapid's MTP text mode, oMLX's SSD cache, and LM Studio's configured context and four parallel slots. Full results and raw data.



rapidmlx.com · Docs · Model mirror · Desktop app · Discord
How it compares
Feature facts only, taken mostly from each project's own documentation as of 2026-09-26 (sources below). For speed, see the measured results above.
| Rapid-MLX | oMLX | Ollama | LM Studio | mlx-lm (mlx_lm.server) |
|
|---|---|---|---|---|---|
| License | Apache-2.0 | Apache-2.0 | MIT | Closed-source app; its MLX engine and lms CLI are MIT |
MIT |
| Inference engine on a Mac | MLX | MLX | GGML/GGUF engine, plus an MLX engine for safetensors models | llama.cpp (GGUF) and MLX engines | MLX |
| Local API | OpenAI (/v1/chat/completions, /v1/responses) and Anthropic Messages (/v1/messages) |
OpenAI and Anthropic Messages | Ollama API, OpenAI-compatible, Anthropic-compatible (subset) | OpenAI-compatible, Anthropic-compatible, LM Studio REST API | OpenAI-style chat API |
| GUI | Rapid-MLX Desktop (macOS app) | macOS menu-bar app and web admin panel | Desktop app (macOS, Windows) | Desktop app | None (CLI / Python) |
| Concurrent requests | Continuous batching | Continuous batching (mlx-lm BatchGenerator) |
Parallel requests per model (OLLAMA_NUM_PARALLEL, default 1) |
Continuous batching (llama.cpp engine; MLX engine since 0.4.2) | Continuous batching (BatchGenerator); one request at a time with a quantized KV cache |
| Prompt / KV cache | Radix prefix cache in memory (with state snapshots for hybrid models), saved to disk on shutdown and restored at startup; quantized KV cache | Tiered KV cache: in-memory hot tier plus SSD cold tier, reused across restarts | Reuses the previous request's prompt KV cache; KV cache quantization (OLLAMA_KV_CACHE_TYPE) |
— | In-memory prompt cache; quantized KV cache (--kv-bits) |
| Tool-call parsing | 27 parser modules, including an auto-detect fallback (rapid_mlx/tool_parsers) |
mlx-lm formats plus the auto-detected families listed in its README | Tool calling | Tool use via the OpenAI-compatible API | Tool calls for models whose tokenizer declares tool-calling support |
Sources: oMLX README ·
Ollama OpenAI and Anthropic compatibility, FAQ, MLX engine ·
LM Studio Anthropic compatibility, parallel requests, 0.4.2 changelog, app terms, mlx-engine ·
mlx-lm server docs and server.py.
Ollama prompt-cache reuse is from our benchmark notes.
— = not verified for this table. Spot an error? Please open an issue.
vs Apple's mlx-lm: per-task results and raw data at https://rapidmlx.com/compare/mlx-lm.
Works with your AI stack
Use Rapid-MLX as a local backend for agents, apps, or your own code. If a client accepts an OpenAI- or Anthropic-compatible endpoint, it can usually use Rapid-MLX without an adapter.
For Claude Desktop, set up its in-app Gateway.






Five Tier-1 agents are exercised end-to-end on real weights before release. See the tested compatibility matrix for exact API coverage and setup status.
Install
Desktop — macOS (Apple Silicon)
The easiest way to chat locally, manage models, and use vision, files, voice, and image generation from one app.
- Download Rapid-MLX Desktop
- Browse signed Desktop releases
- Requires an M-series Mac; Windows and Linux desktop builds are not available yet
- Share Compute setup and credit ledger
CLI and server — macOS (Apple Silicon)
# Homebrew — prebuilt bottle from homebrew-core
brew install rapid-mlx

# Or the guided installer — detects RAM and recommends a starter model
curl -fsSL https://rapidmlx.com/install.sh | bash
Both install the same rapid-mlx CLI. Prefer uv or pip, or want to verify
the installer before running it? See alternative install methods
and install security.
The guided installer prefers a runnable model already cached on this Mac when
it fits the RAM tier. Otherwise its quick first-chat download is
lfm2.5-1b-4bit below 16 GB and qwen3.5-4b-4bit at 16 GB or above; larger
quality picks remain available through rapid-mlx recipe and the model picker.
Submit a Community Benchmark
Help other Mac users choose a model by sharing a standardized result from your own Apple Silicon Mac. Runs stay local until you explicitly choose to publish; you do not need a GitHub account or a benchmark JSON pull request.
- Desktop: Enable Community Benchmark in Settings → Experimental, then choose a model in the Community Benchmark tab, run it, review the result in My Results, and select Publish if you want to share it.
- CLI: Run
rapid-mlx benchmark catalog, thenrapid-mlx benchmark run <model>. Review the saved result and publish it withrapid-mlx benchmark share <run-id>only if you choose to.
Explore the Community Benchmark leaderboard or read the protocol and privacy details.
Quick Start (60 seconds)
1. Chat with a model right now:
rapid-mlx chat
A complete cached chat model that fits this Mac starts without another download. Otherwise Rapid-MLX selects a starter model and downloads its weights before opening the REPL. Type /help for slash commands, /exit to quit.
2. Or serve it for use from other apps:
rapid-mlx serve qwen3.5-4b-4bit
Starts an OpenAI-compatible HTTP server on the first free port in 8000–8009 when --port is omitted. An explicit --port never falls back. The examples below assume port 8000 was selected. Point any client that supports a local custom endpoint (Aider, LangChain, OpenCode, PydanticAI, your own scripts) at http://localhost:8000/v1; Claude Code / Anthropic SDK uses http://localhost:8000 (the Anthropic messages route lives at /v1/messages under the same host).
curl http://localhost:8000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{"model":"default","messages":[{"role":"user","content":"Say hello"}]}'
from openai import OpenAI
client = OpenAI(base_url="http://localhost:8000/v1", api_key="not-needed")
print(client.chat.completions.create(
    model="default",
    messages=[{"role": "user", "content": "Say hello"}],
).choices[0].message.content)
3. Or wire up your coding agent — one command:
rapid-mlx launch claude-code
This saves a private Claude Code profile, starts a local server if needed, and launches Claude Code without editing ~/.claude/settings.json. The same command works after a restart. Swap in codex, opencode, pi, hermes, crush, or goose. For the original config-writing behavior, use --legacy-config; cline and continue-dev keep their existing setup flow.
Cursor: Cursor currently routes BYOK requests through its own servers, so its servers cannot reach a Rapid-MLX endpoint on
localhost. Rapid-MLX therefore does not generate a Cursor localhost config. If you intentionally expose the server through a public HTTPS tunnel, setRAPID_MLX_API_KEY=your-secretfor bothrapid-mlx serve ...andrapid-mlx launch cursor --server-url https://your-public-host. This is no longer a fully local connection; never expose an unauthenticated server. Rapid-MLX rejects explicit local/private addresses but cannot verify reachability from Cursor's network, whose DNS view may differ from your Mac.
Vision / image / video models? They work out of the box with the official installer above (and Rapid-MLX Desktop), which include the vision, image-generation and video-generation runtimes. Audio (TTS, STT, voice cloning) and embeddings ship as opt-in extras. → Optional extras
Not into the terminal? Rapid-MLX Desktop bundles the same engine inside a one-click Mac app.
See it in action
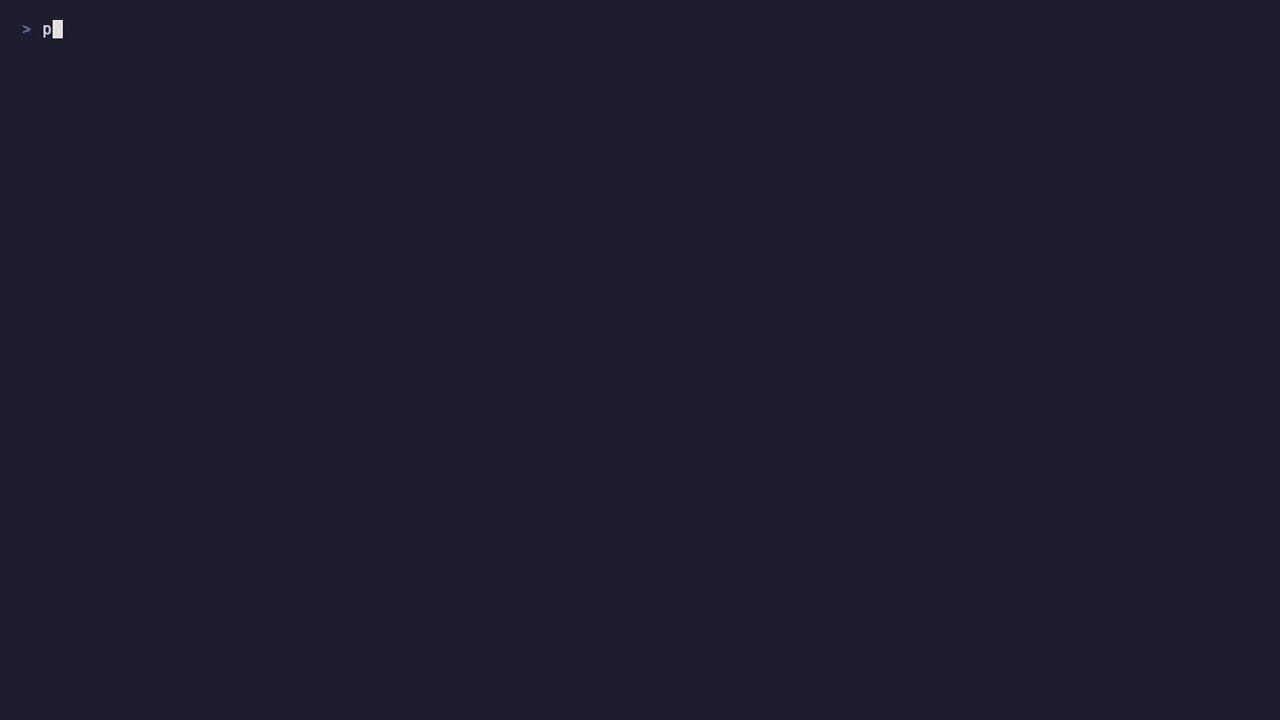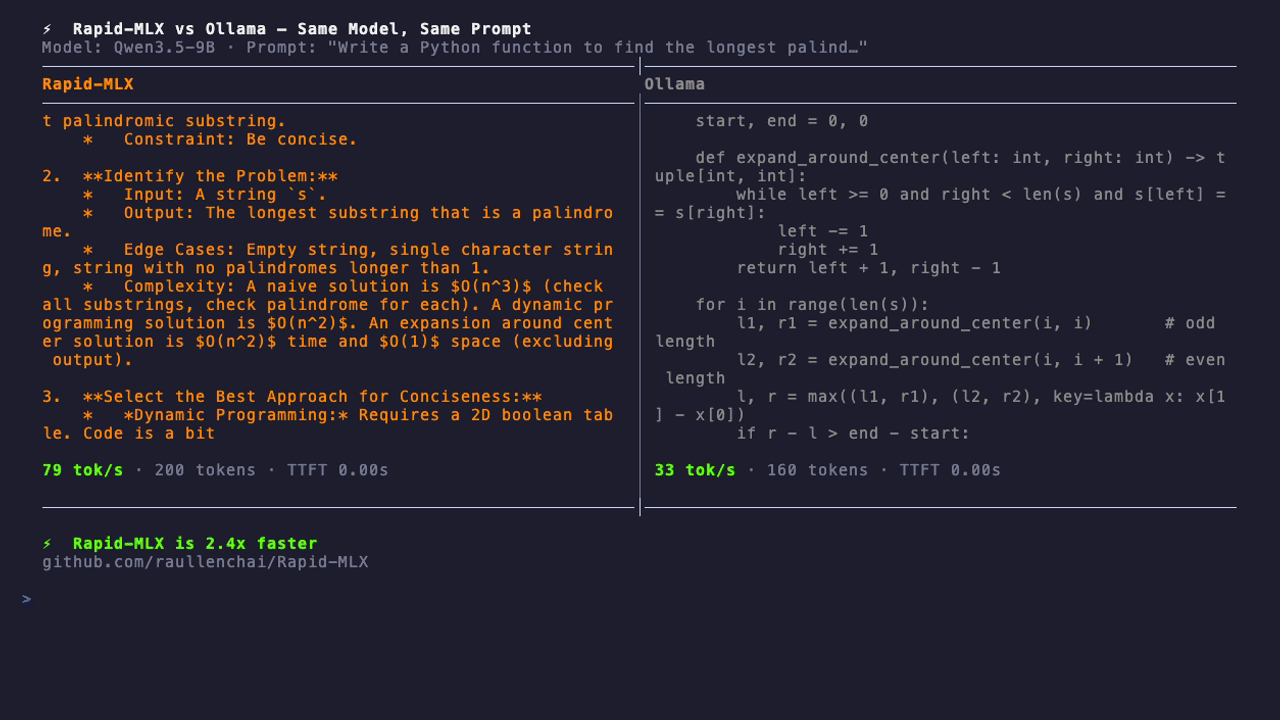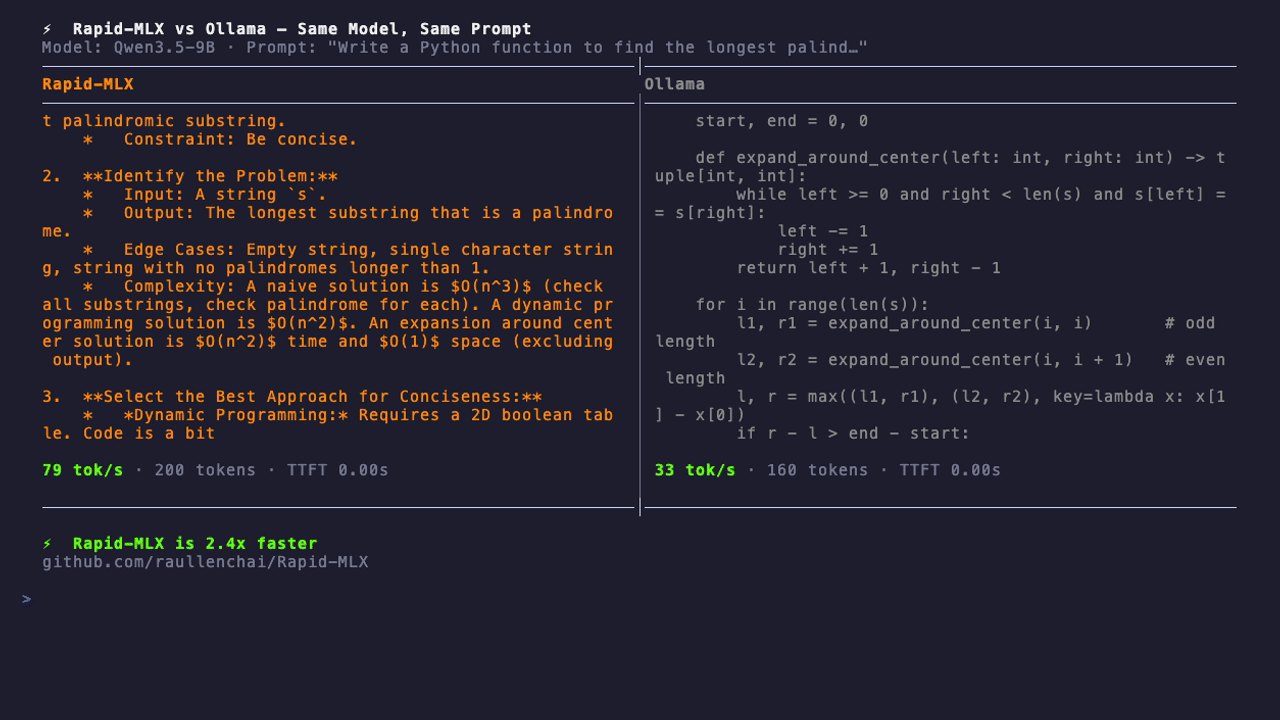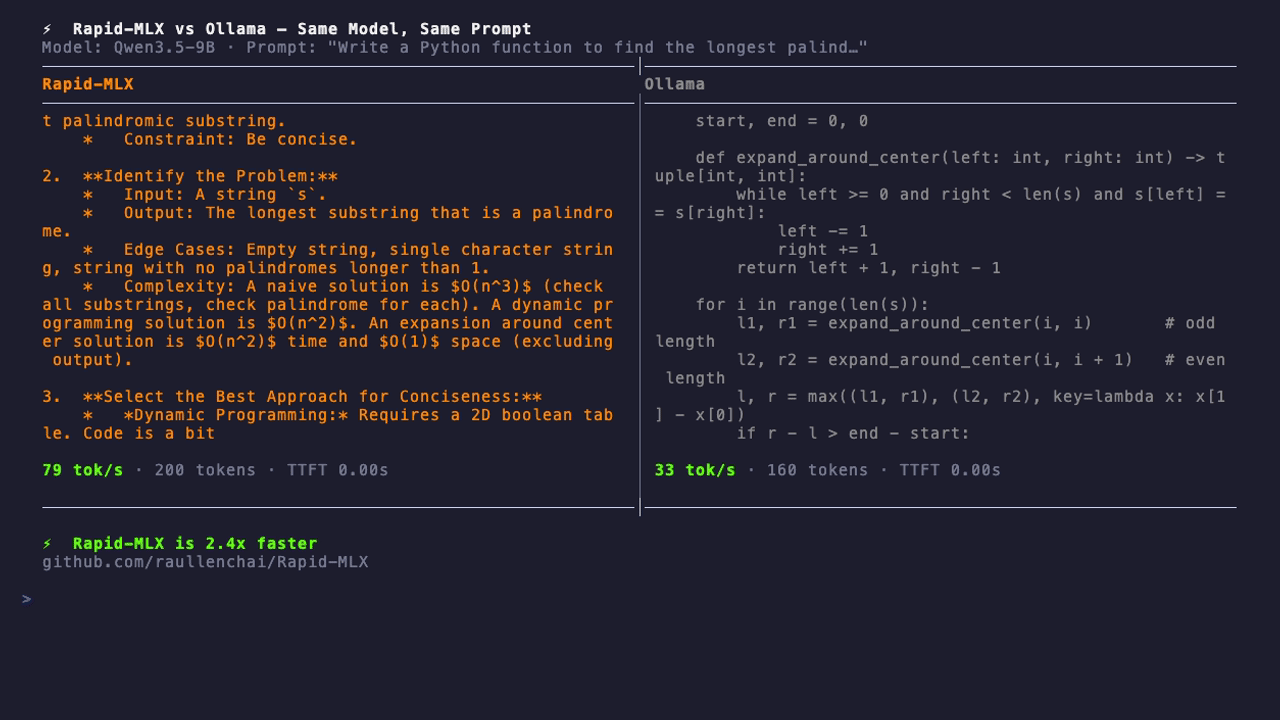
Real session on a Mac mini (M2 Pro, 32 GB), rapid-mlx 0.15.6 from PyPI; idle waits shortened. Recording: docs/assets/demo.cast.
Image generation
Generate images locally from the Desktop Images tab or the OpenAI-compatible Images API. The image runtime ships with the base install:
rapid-mlx serve flux2-klein-4b
curl http://localhost:8000/v1/images/generations \
  -H 'Content-Type: application/json' \
  -d '{"model":"flux2-klein-4b","prompt":"A red sailboat on an alpine lake","size":"1024x1024","seed":42}'
Edit an existing PNG or JPEG with the edit-specialized model:
In one terminal:
rapid-mlx serve qwen-image-edit
In another terminal:
curl http://localhost:8000/v1/images/edits \
  -F [email protected] \
  -F model=qwen-image-edit \
  -F 'prompt=Change the sky to a warm sunset' \
  -F response_format=b64_json
flux2-klein-4b is the recommended starting point. Download sizes are the
currently cataloged model payloads; minimum unified memory includes practical
headroom for macOS and the serving process. Omit steps to use the validated
family default shown below.
| Alias | Best fit | Modes | Download | Minimum unified memory | Default steps |
|---|---|---|---|---|---|
flux2-klein-4b |
Recommended; fast everyday images | Generate + edit | 4.3 GiB | 12 GB | 4 |
bonsai-image-4b-2bit |
Smallest download | Generate | 3.6 GiB | 12 GB | 4 |
z-image-turbo |
Photorealistic images | Generate | 5.5 GiB | 16 GB | 8 |
flux-schnell |
FLUX.1 compatibility | Generate | 9.0 GiB | 16 GB | 4 |
sdxl-base |
SDXL compatibility | Generate | 6.5 GiB | 16 GB | 30 |
flux2-klein-4b-bf16 |
Explicit full-precision Klein path | Generate + edit | 14.9 GiB | 32 GB | 4 |
hidream-o1-dev |
Complex compositions | Generate | 16.4 GiB | 32 GB | 28 |
sd35-large-4bit |
Stable Diffusion 3.5 | Generate | 15.3 GiB | 32 GB | 28 |
qwen-image-2.1 |
Text-rich images on low-memory Macs | Generate + edit | 8.9 GiB | 8 GB | 40 |
qwen-image |
Same model as qwen-image-2.1 |
Generate + edit | 8.9 GiB | 8 GB | 40 |
qwen-image-2.1-bf16 |
Higher-precision Qwen Image 2.1 path | Generate + edit | 30.9 GiB | 32 GB | 40 |
qwen-image-2.1-turbo |
Eight-step distilled Qwen Image 2.1 | Generate | 30.2 GiB | 32 GB | 8 |
qwen-image-edit |
Precise instruction edits and text changes | Edit | 34.9 GiB | 96 GB | 20 |
qwen-image-2.1 uses mflux 0.20 with a native MLX q4 transformer and q4 text
encoder. qwen-image-2.1-bf16 preserves the previous 8-bit-on-load transformer
and bf16 encoder path. qwen-image-2.1-turbo loads the official distilled
checkpoint the same way and samples its published eight-step schedule without
classifier-free guidance; it is text-to-image only. The other two aliases'
edit endpoint performs single-image img2img conditioning; the separate
instruction-edit variant is not yet available upstream. See the family guide for
request and memory behavior.
At 1024×1024 with the four-step Klein default, measured warm generation was
about 9.2 seconds per image on an M3 Ultra. On a 32 GB M2 Pro, the q4 path
measured a 52.7-second median; explicitly selecting
flux2-klein-4b-bf16 reduced that median to 41.8 seconds (1.26× throughput).
The eight-step z-image-turbo baseline was about 34 seconds on the M3 Ultra
and 150 seconds on the M2 Pro.
The q4 alias remains the predictable default; on the measured 32 GB M2 Pro,
use the larger 14.9 GiB BF16 alias when latency matters. Exact results depend
on resolution, power/thermal state, and other workloads. The server completion
log reports total time and, when the backend exposes exact loop boundaries,
measured denoise s/step. For the qualified 1024-square Klein shape it also
reports estimated achieved TFLOPS; unavailable or unqualified values are never
fabricated.
→ Reproducible precision benchmark and methodology
Image work is single-flight: one generation runs at a time so two diffusion pipelines cannot exhaust unified memory. Model weights retain their own licenses and use restrictions; review the upstream model card before commercial deployment.
→ Release dogfood coverage and reproducible acceptance contract
Video generation
Run text-to-video or image-to-video locally through the OpenAI-compatible
Videos API. Three backends ship — Wan 2.1 / 2.2, CogVideoX-Fun and
LTX-2.3 — across 8 registered checkpoints. wan2.2-ti2v-5b-q8 is the
recommended starting point: smallest of the Wan set, and TI2V means one
checkpoint does both text-to-video and image-to-video.
The video runtime ships with the base install. Install ffmpeg for the final MP4
mux.
brew install ffmpeg
rapid-mlx serve wan2.2-ti2v-5b-q8
Create and download a clip:
curl http://localhost:8000/v1/videos \
  -F model=wan2.2-ti2v-5b-q8 \
  -F 'prompt=A fox running through fresh snow, cinematic tracking shot' \
  -F seconds=1 \
  -F size=832x512

# Poll until GET /v1/videos/VIDEO_ID reports "status": "completed", then:
curl http://localhost:8000/v1/videos/VIDEO_ID/content -o output.mp4
The create call returns a job immediately. Poll GET /v1/videos/VIDEO_ID
until status is completed. Add -F [email protected] for
image-to-video.
Generation is serialized — one clip at a time — because two diffusion pipelines resident at once will exhaust unified memory. Expect minutes of compute per second of footage, not real time.
→ Every checkpoint, RAM requirement and tuning knob
Audio: speech, transcription, voice cloning
The dependency commands below use the official install.sh environment. For Homebrew or another install method, follow optional extras.
44 audio aliases behind the OpenAI-compatible /v1/audio/* endpoints — any
OpenAI SDK works unchanged.
~/.rapid-mlx/bin/python -m pip install 'rapid-mlx[audio]'

# Text to speech
rapid-mlx serve kokoro
curl http://localhost:8000/v1/audio/speech \
  -H "Content-Type: application/json" \
  -d '{"model":"kokoro","input":"hello from rapid-mlx"}' --output hello.wav

# Transcription (Whisper / Parakeet / SenseVoice)
rapid-mlx serve whisper-large-v3-turbo
curl http://localhost:8000/v1/audio/transcriptions \
  -F [email protected] -F model=whisper-large-v3-turbo
Beyond the basics, three things you may not expect to run locally:
- Zero-shot voice cloning from a reference clip.
indexttsis the only one that takes the clip alone;qwen3-tts-clone,f5-tts-zhandchatterboxall requireref_text(the clip's exact transcript) paired withref_audio, and the request is rejected before generation if it is missing. - Voice design —
qwen3-tts-voicedesignhas no named speakers at all. Describe the voice you want in natural language viainstructions(timbre, gender, age, accent, emotion, prosody) and it synthesises it. - Forced alignment —
qwen3-alignertakes audio plus the transcript you already have and returns per-character timings. It never guesses at the words, so it cannot mis-hear them; that is what karaoke captions and beat-synced editing need.
Also: word-level timestamps on transcription, and local text-to-music at
/v1/audio/music.
→ All 44 aliases across 13 families
Typed decisions with System One
Serve fast noul, choice, and score decisions through a
TypeSafe-compatible /v1/systemone API. Laya-MLX is the compact default;
CLM-8B uses a native MLX Qwen3-8B encoder and cached state/action projections.
Cloudflare Clef adds joint-schema decisions from text, images, and video frames,
on native MLX or with its official head on Torch/Metal. Decider-2b and
OpenJev (27B, non-commercial weights) run on native MLX with no extra install.
For the official install.sh environment, use the commands below. Other install methods follow optional extras.
~/.rapid-mlx/bin/python -m pip install 'rapid-mlx[system-one]'
rapid-mlx system-one convaiinnovations/laya
# Decider needs no extra:
rapid-mlx system-one decider-2b
# OpenJev 27B, text only; weights are CC BY-NC 4.0 (non-commercial):
rapid-mlx system-one openjev
# Cloudflare Clef on native MLX (4-bit weights), no extra install:
rapid-mlx system-one clef-flash-mlx
# Or with the official Torch head (bf16 weights):
~/.rapid-mlx/bin/python -m pip install 'rapid-mlx[clef]'
rapid-mlx system-one clef-flash
CLM uses a converted copy of its upstream projection head and does not require PyTorch or vLLM while serving.
→ Laya, CLM, Decider, OpenJev, and Clef setup, API examples, and compatibility limits
Why Rapid-MLX
| Apple-Silicon-native | Pure MLX kernels — no llama.cpp fallback, no Metal shim. Continuous batching, prompt cache (radix + DeltaNet RNN snapshots), and a quantized live KV cache (int4/int8 on the continuous-batching cache + TurboQuant K8V4 codec) run at native MLX bandwidth on M1 → M4. |
| Drop-in OpenAI / Anthropic API | /v1/chat/completions, /v1/responses (Codex CLI), /v1/messages (Anthropic SDK / Claude Code), /v1/embeddings, /v1/rerank (Cohere/Jina shape), /v1/audio/*, /v1/videos — same wire as ChatGPT / Claude, no client adapter. |
| First-class ecosystem coverage | 12 agent CLIs and 3 Python frameworks are wire-verified against real weights every release (5 are Tier-1, re-verified on current binaries) — Codex CLI, Claude Code, OpenCode, Qwen Code, OpenHands, Hermes Agent, Aider, Kilo Code, DeepSeek Harness, GitHub Copilot, Factory Droid, Moonshot Kimi Code + LangChain, PydanticAI, smolagents. |
Use Cases
| Chat in the terminal | rapid-mlx chat qwen3.5-9b-4bit |
Streaming REPL, /help for slash commands, --think / --no-think to control CoT. |
| OpenAI server for your apps | rapid-mlx serve qwen3.5-9b-4bit |
OpenAI-compatible API at http://localhost:8000/v1 — point Aider, LibreChat, LangChain, or any OpenAI SDK client at it. |
| Agent backends | rapid-mlx serve qwen3.6-35b-8bit &rapid-mlx agents codex --setup && codex |
14 clients, including Cline, Goose, and Crush, auto-configure via agents <name> --setup once the server is up (12 in the family matrix, 5 Tier-1) — see Agent support. |
| Benchmark your Mac | rapid-mlx benchmark run qwen3.5-9b-4bit |
Reproducible model-first benchmark; saves privately, with a separate consent-gated benchmark share RUN_ID. |
→ One-shot IDE setup with rapid-mlx launch <claude-code|cline|continue-dev>; agent setup also supports rapid-mlx agents cline --setup, rapid-mlx agents kilo-code --setup, and rapid-mlx agents continue --setup. See the Cline, Kilo Code, and Continue guides.
Agent Support
All 12 agents below are wire-verified against real weights every release via their own integration-test cell. Of these, five are Tier-1 — Claude Code, Codex CLI, Hermes, Aider, and DeepSeek Harness — re-verified end-to-end against the current client binary every release, with one guardian per API wire (Anthropic /v1/messages, OpenAI /v1/responses, and /v1/chat/completions covered for tool-calling depth, reach, and DeepSeek's own harness protocol). The other seven are Tier-2: wire-verified in the matrix and configured on-demand. The first nine agents each ship a rapid-mlx agents <name> --setup config template (except Claude Code, which is one env-var). Cline, Continue.dev, and Pi also have one-command setup, though none is part of the 12-agent family matrix; GitHub Copilot, Factory Droid, and Moonshot Kimi Code plug in through their own documented BYOK config (auth-gated, so the matrix cell is a wire smoke).
Tier-1 is not a label — it is a job that blocks the release. tests/integrations/agent_smoke.sh drives each of the five through the same real multi-step bug-fix task against a local 35B model and asserts the repo's own test suite goes green afterwards; if any one of them fails, the version cannot tag or publish.
Tier-1 (5): Claude Code · Codex CLI · Hermes · Aider — last re-verified end-to-end 2026-07-28 on current binaries (claude 2.1.211, codex 0.145.0, hermes 0.9.0, aider 0.86.2). DeepSeek Harness — promoted 2026-08-17, verified on dsh 0.1.0-rc.7 against qwen3.6-35b-8bit.
Tier-2 (7): OpenCode · Qwen Code · OpenHands · Kilo Code · GitHub Copilot · Factory Droid · Moonshot Kimi Code.
Pi Coding Agent also has one-command local setup with
rapid-mlx agents pi --setup and an OpenAI-compatible /v1/chat/completions route. See the
Pi guide. Pi is not yet a cell in the 12-agent family
matrix below.
| Agents (12) | Frameworks (3) |
|---|---|
| Codex CLI · Claude Code · OpenCode · Qwen Code · OpenHands · Hermes Agent · Aider · Kilo Code · DeepSeek Harness · GitHub Copilot · Factory Droid · Moonshot Kimi Code | LangChain (+ LangGraph) · PydanticAI · smolagents |
Also compatible with OpenAI-compatible clients that allow direct local endpoints via http://localhost:8000/v1 — LibreChat, Open WebUI, and more plug in with a single URL change.
Goose and Crush have setup profiles for a local server. After rapid-mlx serve qwen3.5-4b-4bit, run rapid-mlx agents goose --setup or rapid-mlx agents crush --setup in another terminal. See the Goose and Crush guides for the config paths and launch commands. These are separate from the 12-agent release matrix above.
→ Full 12-agent + 3-framework matrix (test cells + xfail reasons) → Codex CLI · Claude Code · OpenCode · Qwen Code · OpenHands · Hermes · Aider · Kilo Code · DeepSeek Harness · Copilot · Droid · Kimi Code
For OpenHands CLI 1.x, run rapid-mlx agents openhands --setup, export the printed values, then use openhands --override-with-envs. The flag is required for the CLI to use those values; see the OpenHands guide. The published matrix's OpenHands cells use a pinned 0.9.0 Docker image.
For Aider, rapid-mlx agents aider --setup prints OPENAI_API_BASE, OPENAI_API_KEY, and an openai/-prefixed AIDER_MODEL; see the Aider guide. DeepSeek Harness uses the Cordis patch setup.
Latest Large-Model Benchmarks
Single-request (B=1) serving on a 256 GB M3 Ultra, with one 4-bit model
resident. Each row is the median of three requests after server readiness,
with the prefix cache cleared before every run. These are local serving
measurements, not model quality scores. All three rows target an 8K prompt and
256-token decode; after chat templating the Qwen prompts contain 8,156 tokens
and the GLM prompt contains 8,192.
| Model | Shape | Median TTFT | Prefill | Decode | MLX memory observed through 32K |
|---|---|---|---|---|---|
qwen3.8-27b-4bit |
27B dense | 24.66s | 330.8 tok/s | 43.4 tok/s | 26.7 GB active / 27.1 GB peak |
qwen3.8-flash-next-4bit |
180B total / 6B active¹ | 9.40s | 867.9 tok/s | 23.0 tok/s | 102.8 GB active / 148.1 GB peak |
glm5.3-flash-4bit |
320B total / 18B active | 22.78s | 359.6 tok/s | 27.8 tok/s | 180.6 GB active / 195.6 GB peak |
The biggest 0.13.4 gain is Qwen3.8-27B's verified MTP path. On the same model, Mac, dependency versions, prompts, and cache-clear procedure:
| Prompt | 0.13.3 decode | 0.13.4 decode | Speedup | TTFT (0.13.3 → 0.13.4) |
|---|---|---|---|---|
| 128 | 30.71 tok/s | 43.93 tok/s | 1.43× | 0.54s → 0.51s |
| 2K | 28.88 tok/s | 44.69 tok/s | 1.55× | 6.18s → 6.07s |
| 8K | 24.58 tok/s | 43.38 tok/s | 1.77× | 25.04s → 24.66s |
| 32K | 16.52 tok/s | 38.66 tok/s | 2.34× | 110.25s → 109.12s |
¹ Flash-Next comprises a 125B language model, 51B n-gram embedding, and 4B MTP head. Its default autoregressive path was effectively flat between the two builds; separately qualified MTP and prompt-lookup modes remain workload-dependent.
Flash-Next prefill reaches 262 / 875 / 868 / 716 tok/s at 128 / 2K / 8K / 32K; median TTFT is 0.35 / 2.30 / 9.40 / 45.73s. Its 99 GB quantized weights make 192 GB the practical recommended tier; 128 GB is tight and was not physically tested. GLM-5.3-Flash reached 27.2 tok/s decode at 32K, but its TTFT was 118.34s and its 195.6 GB allocator peak leaves no safe system headroom on a 192 GB Mac. Use a 256 GB Mac for this measured 32K workload; 192 GB remains the catalog floor for shorter contexts. Qwen3.8-27B remains the 32 GB recommendation for the standard approximately 8K workload; its 32K automatic MTP path was not physically qualified on a 32 GB Mac.
→ Environment, exact methods, full context curves, and qualification notes
M4 Pro 48 GB Community Benchmarks
Nine public measurements were run on a 12-CPU / 16-GPU-core Apple M4 Pro with
48 GB unified memory using the unmodified PyPI rapid-mlx==0.14.1 release.
The text rows are single-request (B=1) Community Benchmark v2 medians: one warmup
plus five measured rounds per case, greedy decode, prefix cache off, and no
speculative decoding. The Mac was on AC power with nominal thermals and normal
memory pressure throughout.
| Model | 512 prompt → 128 output | 2K prompt → 512 output | Peak active memory |
|---|---|---|---|
qwen3.5-4b-4bit |
0.75s TTFT / 83.45 tok/s | 2.95s / 82.02 tok/s | 4.4 GiB |
qwen3.5-9b-4bit |
1.37s / 49.76 tok/s | 5.59s / 48.68 tok/s | 6.7 GiB |
gemma-4-12b-4bit |
2.19s / 31.87 tok/s | 9.16s / 30.92 tok/s | 11.9 GiB |
gpt-oss-20b-mxfp4-q8 |
0.75s / 73.24 tok/s | 2.82s / 70.10 tok/s | 12.4 GiB |
gemma-4-26b-4bit |
0.78s / 75.59 tok/s | 3.06s / 71.33 tok/s | 16.9 GiB |
qwen3.6-27b-4bit |
4.87s / 15.53 tok/s | 19.25s / 15.30 tok/s | 18.1 GiB |
qwen3.8-27b-4bit |
4.87s / 15.53 tok/s | 19.31s / 15.28 tok/s | 18.4 GiB |
The same released CLI completed a 1024x1024 FLUX.2 Klein 4B image in 272.34s and an 832x480, 81-frame Wan2.2 TI2V 5B video job in 15m57.53s. These use registered image/video protocols and are complete job times, so they are not throughput comparisons with the text table.
Normal Qwen3.8 serving also activated its pinned MTP path. In a separate same-model A/B, the repeated-run median improved from 13.0 to 17.2 tok/s (+32.3%). This serving workload differs from the fixed public protocol; the full record shows every observation and the acceptance metrics.
Run any row as a local server with rapid-mlx serve <alias>. To reproduce the
fixed benchmark instead, preview its exact workload first:
rapid-mlx benchmark plan qwen3.5-9b-4bit
rapid-mlx benchmark run qwen3.5-9b-4bit
rapid-mlx benchmark share <run-id>   # previews the payload; default is No
Normal serving can enable qualified per-model accelerations that this fixed, non-speculative protocol deliberately excludes, so do not compare this table directly with the MTP serving measurements above. All nine public rows include the Rapid-MLX version, run conditions, and anonymous submission ID. The seven text rows also expose resolved model revisions; the generation rows currently report unresolved identity in the public projection, with their exact local snapshot revisions preserved in the full record.
→ Full methodology, revisions, commands, and public submission IDs · Community Benchmark board
Choose Your Model
The installer and desktop app use the same RAM-tier recommendation catalog. Run rapid-mlx recipe to see its Smart and Fast picks for this Mac (--max-ram 32 simulates another tier; --json is machine-readable). If you want to shop the full catalog: rapid-mlx models lists every alias, rapid-mlx info <alias> shows the per-alias profile (parser, MoE / hybrid flags, KV codec eligibility, speculative-decoding gates).
Current Smart picks by unified memory:
- 8 GB and up:
lfm2.5-2.6b-4bit—rapid-mlx serve lfm2.5-2.6b-4bit - 16 GB and up:
qwen3.5-4b-4bit—rapid-mlx serve qwen3.5-4b-4bit - 18 GB and up:
qwen3.5-9b-4bit—rapid-mlx serve qwen3.5-9b-4bit - 24 GB and up:
bonsai-27b-2bit—rapid-mlx serve bonsai-27b-2bit - 32 GB and up:
qwen3.8-27b-4bit—rapid-mlx serve qwen3.8-27b-4bit
This table is the same one the desktop app's picker reads, and the installer
prints the matching line for your Mac — a CI test parses both files and fails
if they drift apart. Measured rows use the standard ~8K prompt peak of the
complete rapid-mlx serve process tree on an M2 Pro 32 GB Mac mini (the 32 GB+ row: M3 Ultra, 2026-08-18 — footprint is config-bound, speed reads lower on smaller chips).
| RAM | Recommended | Peak RSS | One-shot |
|---|---|---|---|
| 8–15 GB MacBook Air / base Mini | lfm2.5-2.6b-4bit |
3.0 GB | rapid-mlx serve lfm2.5-2.6b-4bit |
| 16–17 GB MacBook Air / Pro | qwen3.5-4b-4bit |
6.0 GB | rapid-mlx serve qwen3.5-4b-4bit |
| 18–23 GB MacBook Pro | qwen3.5-9b-4bit |
8.7 GB | rapid-mlx serve qwen3.5-9b-4bit |
| 24–31 GB Mac Mini / MacBook Pro | bonsai-27b-2bit |
13.0 GB | rapid-mlx serve bonsai-27b-2bit |
| 32 GB+ Mac Studio / MacBook Pro | qwen3.8-27b-4bit |
20.0 GB | rapid-mlx serve qwen3.8-27b-4bit |
The experimental deepseek-v41-flash-reap-2bit alias is a separate
256 GB Mac Studio lane, not a recommendation for the table above. It pins the
199 GiB REAP checkpoint and its separate 4.62 GB mixed-precision DSpark
sidecar, refuses to start below
224 GiB unified memory, and serves deterministic greedy K4 decoding through a
serial OpenAI-compatible endpoint:
rapid-mlx pull deepseek-v41-flash-reap-2bit
rapid-mlx serve deepseek-v41-flash-reap-2bit
The mixed head keeps routed experts at 2-bit and raises the smaller dense paths to 4-bit. Sustained four-workload qualification measured 19.39 tok/s overall at K4 versus 9.58 tok/s autoregressive (2.02x), with a 218.23 GB peak. This is approximately 20 tok/s for the measured configuration, not a per-prompt guarantee. This lane remains experimental and text-only, caps input at 8,192 tokens and output at 4,096, and does not claim sampling, tool calling, MCP, or continuous batching.
Every Mac from 32 GB up gets the same pick, and that is the point: Qwen3.8-27B
scores 52 on the Artificial Analysis Intelligence Index (2026-08-18) —
GPT-5.6-class, the highest of any open-weights model we serve, ahead of the
much larger 122B (33) and 35B (32) it replaces (the index scores the
full-precision release; our 4-bit build's deltas are unmeasured — the
standing caveat for every quantized pick here). On the measured 8K workload it
prefills at 330.8 tok/s and decodes at 43.4 tok/s, with zero new swap. The
verified 4-bit artifact automatically enables its MTP path when the selected
cache and serving lane are compatible; --no-spec-decode remains the explicit
opt-out. The 32 GB recommendation is based on the approximately 8K
qualification (about 20 GB for the complete process tree). The 32K Studio run
reached a 27.1 GB MLX allocator peak before non-MLX process and macOS memory;
on a 32 GB Mac, reduce context/cache use or choose a larger-memory machine.
M1 and M2 Macs can explicitly select qwen3.8-27b-4bit-fp16. It carries the
same 4-bit target and native MTP layout, but stores the checkpoint's
non-quantized tensors as FP16 for chips without accelerated BF16 matrix
multiplication. The regular qwen3.8-27b-4bit alias remains unchanged for M3
and newer Macs; Rapid does not silently swap checkpoint precision.
The pinned ornith-1.5-122b-a10b-4bit alias offers the publisher’s 122B hybrid MoE checkpoint on Macs with at least 96 GB unified memory. Install the [vision] runtime for its checkpoint loader; this alias qualifies text chat, streaming, tools, and thinking controls. Its download is about 69.6 GB. See the October 27 qualification record for results and the two excluded candidates.
→ Full RAM tier map + serve flags per tier → Every alias, quant, and family (216 text + 13 image + 10 video + 44 audio aliases, 283 total) · interactive at models.rapidmlx.com
Alternative install methods
The two paths above cover most users — reach for these only if you already manage Python yourself.
Homebrew — Mac-native, one command, prebuilt bottle from homebrew/core
brew install rapid-mlx
Ships in homebrew-core since 0.10.12 — no tap, no trust prompt. Upgrade with brew upgrade rapid-mlx. If you previously installed from the legacy raullenchai/rapid-mlx tap, switch once: brew uninstall rapid-mlx && brew untap raullenchai/rapid-mlx && brew install rapid-mlx.
uv — isolated tool install, auto-manages Python
uv tool install rapid-mlx@latest
Don't have uv yet? curl -LsSf https://astral.sh/uv/install.sh | sh. Upgrade with uv tool upgrade rapid-mlx.
pip — requires Python 3.12+ (macOS ships 3.9)
python3.12 -m pip install rapid-mlx
If python3.12 is missing, use the official installer above or install Python 3.12 with Homebrew first. Upgrade a Python 3.12 installation with python3.12 -m pip install -U rapid-mlx.
Image-input / VLM models (Qwen-VL, Gemma 4, true multimodal) need no extra step — the vision runtime ships with the base install. See Optional extras for audio and embeddings.
For the complete feature set — chat, embeddings, audio, and System One on top of the base install — install the [all] extra: python3.12 -m pip install 'rapid-mlx[all]'. Audio alone is python3.12 -m pip install 'rapid-mlx[audio]'; see Optional extras.
Command Reference
rapid-mlx --help                    # top-level command list
rapid-mlx <subcommand> --help       # per-subcommand flags
Covers chat, serve, system-one, share, agents (setup / test), bench, recipe, models, ls, pull, rm, alias, ps, info, connect, doctor, upgrade, telemetry, and launch.
→ Full CLI reference with every flag
Troubleshooting
Run the built-in self-check first:
rapid-mlx doctor
Top three things that go wrong:
- Much slower than expected. Qwen3.5 / 3.6 default to thinking-on — add
--no-thinkto skip chain-of-thought. → Slow tok/s - Out of memory. Model too big for your RAM — pick a smaller quant from Choose Your Model or the full tier map. → OOM guide
- Tool calls arriving as plain text. Auto-recovery handles most cases; if not, set
--tool-call-parserexplicitly for your model. → Tool-call recovery
→ All troubleshooting entries (OOM, empty responses, slow TTFT, port taken, shell completion, HF cache, and more)
Community & Support
- Discord: Join the Rapid-MLX community for live help and local-AI discussion.
- Tell us what you want: run
rapid-mlx feedback(or--no-opento just print the link) — it opens that same Discord invite. Telemetry can only show us what people do; the Discord is where you tell us why. - Twitter / X: Follow @rapidmlx for releases, benchmarks, and project updates.
- Questions & builds: Ask or share in GitHub Discussions.
- Feedback & ideas: Report a bug, request a model, or propose a feature.
- Security: Send sensitive reports through a private advisory; see SECURITY.md.
- Contributing: Start with CONTRIBUTING.md. Explore compatible benchmark models with
rapid-mlx benchmark catalog; runs stay local unless you explicitly share one in the internal beta. - Show support: Star this repository to follow releases and help others discover the project.
Privacy: Anonymous, metadata-only telemetry is on by default in 0.15.0 and
is documented in Settings → Privacy. The desktop app sends its events to
rapidmlx.com's telemetry service, while the engine sends
privacy-hardened batches to PostHog Cloud (US). Turn it off in Settings →
Privacy, with rapid-mlx telemetry off, RAPID_MLX_TELEMETRY=0, or
DO_NOT_TRACK=1. Prompts, completions, paths, IP addresses, locations, and API
keys are never collected, and no per-person profile is built. See
what we do and don't collect.
Contributors
Every avatar here shipped something in Rapid-MLX — model support, tool-call parsers, fixes, docs, and benchmark submissions. Thank you.
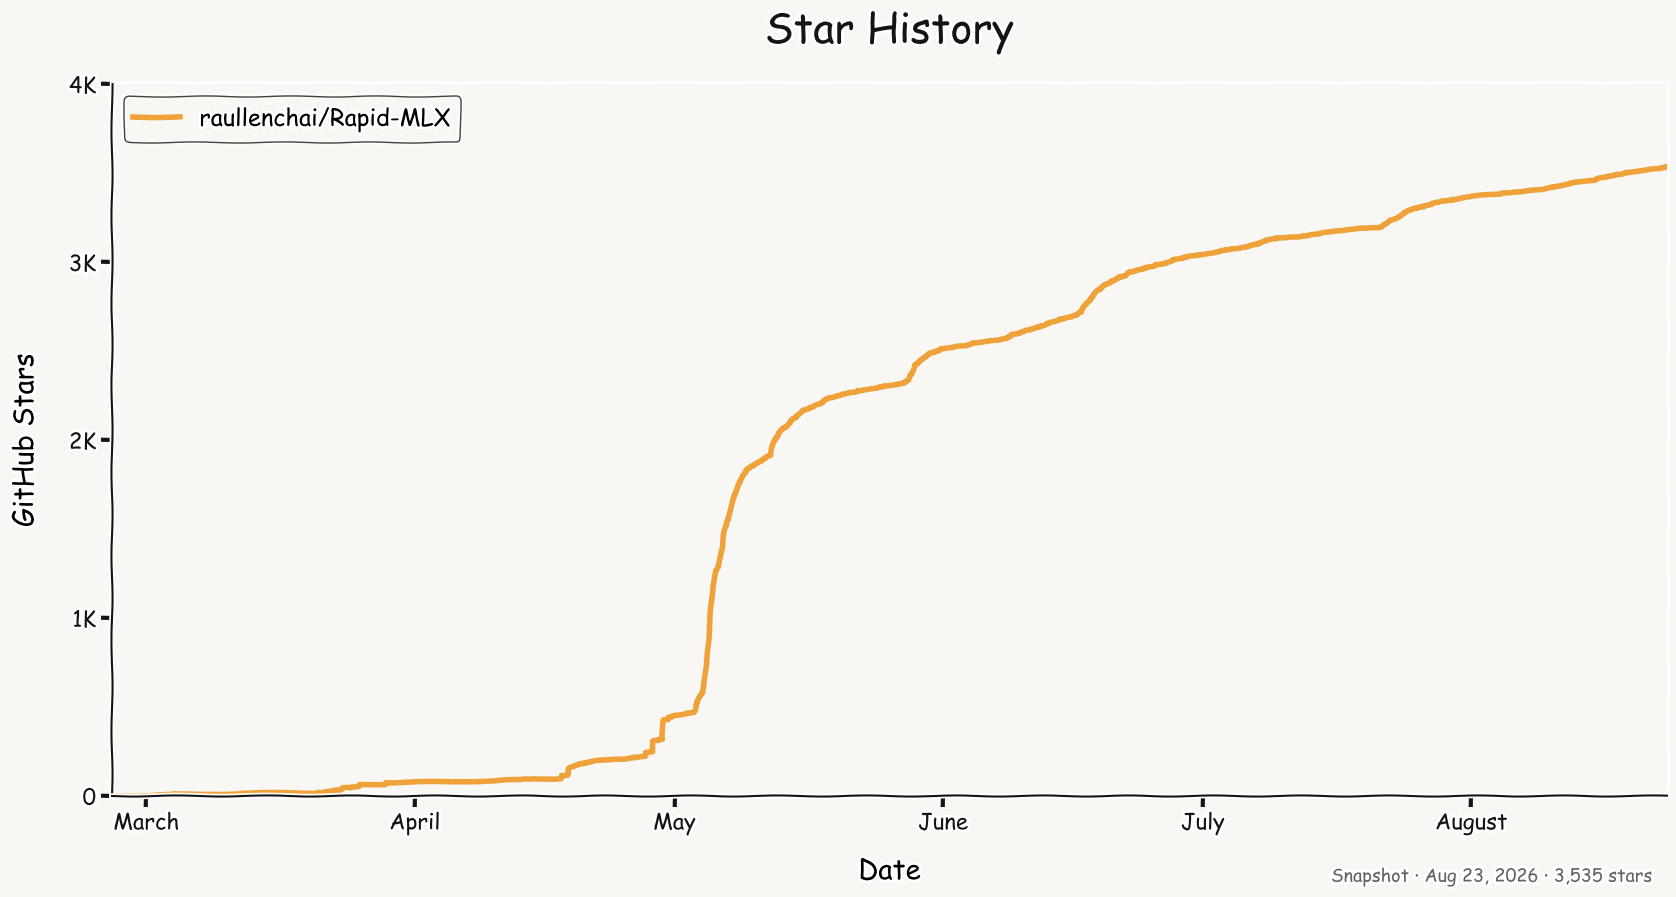
Star History
Acknowledgements
Rapid-MLX began as vLLM-MLX by
Wayner Barrios, which is where this repository's
history starts and where the engine's paged KV cache, prefix cache, and
continuous batching were first built. It was renamed to Rapid-MLX on 2026-03-13,
now ships as the rapid-mlx package (import name rapid_mlx), and has been
extensively modified and in large part rewritten since (see NOTICE).
Thank you.
It stands on Apple's MLX stack and the runtimes built around it:
- MLX — Apple's array framework for Apple Silicon
- mlx-lm — LLM inference, KV cache, quantization
- mlx-vlm — vision-language models
- mlx-audio — speech and audio models
Vendored third-party components and their licenses are listed in NOTICE; what the macOS app ships is enumerated in apps/rapid-mac/THIRD_PARTY.md.
License
Apache 2.0 — see LICENSE and NOTICE.
Experimental persistent chat
The harness is included in the base install. Try it with a local inference server:
python -m pip install rapid-mlx
rapid-mlx serve mlx-community/Qwen3.5-4B-MLX-4bit --port 18800
# In another terminal:
rapid-mlx chat --harness --base-url http://127.0.0.1:18800 --profile dogfood
rapid-mlx chat --harness --base-url http://127.0.0.1:18800 --profile dogfood --resume last
The usual model selection and startup also work with rapid-mlx chat --harness.
The existing chat experience remains the default; RAPID_MLX_CHAT_HARNESS=1
enables the experimental harness for subsequent chat commands.
The harness reads the selected model's native context and effective serving
limit from /v1/models before each turn. Its default context budget is the
smaller of those limits and 32,768 tokens. Newly spawned harness chat servers use the
same default, bounded by locally cached model metadata. A server started with
--context-length remains authoritative; set that flag on serve when
attaching to an existing server. An explicit chat startup context can exceed
the default budget, but cannot exceed the model or serving limit or the
harness ceiling of 131,072 tokens. The runtime
counts tokens using the inference server when available and falls back to a
conservative text estimate. It reserves room for the answer, compacts older
tool outputs, and saves summary checkpoints to keep longer conversations usable.
Use /context for the system/tools, conversation, tool-output, and free-token
breakdown; /compact [instructions] saves a summary checkpoint manually. A dim
context indicator appears at 50% usage, with a warning at 90%. Automatic
compaction announces itself in the transcript.
Responses stream as Markdown. Ctrl-C stops the current response. Use /history
to list and resume conversations, /new to start fresh, /edit and /regen to
create branches, and /branch to switch between them. /think on turns thinking
on; /think off turns it off. The prompt is › , or Thinking › while thinking
is on (> replaces › on non-UTF-8 output). Thinking is collapsed by default
and /show-thinking expands it for the current session; it is never saved.
The folder where you start a new conversation becomes its workspace and stays
fixed when you resume it. Ask Rapid to read files, search code with a regex, or list
matching paths using its built-in read_file, grep, and glob tools. Reads
support text/code, PDF text, DOCX, XLSX/CSV, PPTX, JSON/YAML, and HTML. Results
include line numbers and paging hints; searches honor .gitignore and skip
binaries and dependency folders. These three read tools need no approval.
Paths outside the workspace and secrets-like paths are refused, including
symlink escapes. Use /attach PATH to explicitly share a file from another
folder (or a sensitive file you choose to share). Attachments accept the same
formats up to 20 MiB and save an extracted text snapshot capped at 1 MiB.
Spreadsheet extraction caps each sheet at 1,000 rows/10,000 cells and reads
cached formula values; it does not calculate formulas. PNG, JPEG, WebP, and GIF
images work with vision models. Only the current message’s images are sent;
earlier images become placeholders. Scanned PDFs without text are unsupported. /regen reruns workspace reads, so it
can see file changes; attached snapshots stay fixed.
/export [PATH] exports the selected branch as Markdown; /help lists commands.
New conversations show New chat · Type / for commands; resuming shows the
conversation title. Type / to browse commands in the completion menu.
History is stored under ~/Library/Application Support/Rapid/chat/<profile>/
(RAPID_MLX_CHAT_HOME overrides the root). A separate local owner starts
automatically, survives client exits, and stops after five idle minutes.
An owner restart preserves history and marks an in-flight answer interrupted;
you can continue or regenerate. Only local HTTP inference targets are supported.
New conversations use the CLI's launch directory (resolved to its real path) as
an immutable workspace, including after resume. write_file and patch edit
UTF-8 files up to 1 MiB with durable pre-images; /undo restores the last file
edit, refusing to overwrite subsequent changes. Repeat /undo for earlier edits.
It does not undo shell commands or Python effects. Older conversations without a
workspace can bind one explicitly supplied client directory on their next turn;
that directory then remains immutable. The owner never chooses its own cwd.
Workspace edits and commands without dangerous patterns run immediately.
Outside-workspace and secrets-like file reads/edits are refused, even with approval.
Explicit attachments grant access only to their extracted snapshot. Destructive commands,
privilege changes, remote execution/uploads, and side effects on regenerated or
edited branches require approval once each. Approvals show a command or diff:
y allows once, a allows the exact tool/arguments for this conversation when
offered, and n denies (N adds an optional denial reason). Dangerous actions
never offer a. Ctrl-C cancels a
pending approval or kills the running command's process group. Unanswered
approvals expire after 120 seconds; noninteractive input denies them.
terminal and execute_code(language="python", code=...) run noninteractively
in the workspace, with a 120-second default timeout (maximum 600) and 8 KiB of
head/tail output. Python uses python3 on PATH, falling back to the bundled
interpreter. Terminal processes inherit only PATH, HOME, USER, LOGNAME, LANG,
LC_, TERM, SHELL and TMPDIR; PWD is set to the workspace. To pass other
non-secret variables, set
RAPID_MLX_HARNESS_TERMINAL_ENV in the owner environment to a comma-separated
list of exact names before starting the owner. Names containing KEY, SECRET,
TOKEN, PASSWORD, PASSWD, CREDENTIAL or AUTH, AWS_ and DATABASE_URL are always
excluded, as are values containing URL userinfo. This limits accidental
inheritance; commands can still access files and resources available to the user.
Pattern checks are heuristics, not an OS sandbox; scripts and
programs run with your local account's access. Use
RAPID_MLX_CHAT_APPROVALS=always or --approvals always to approve every action;
RAPID_MLX_CHAT_ACTION_TOOLS=0 or --no-action-tools disables all four tools.
These client settings also apply when attaching to an existing owner; an owner's
stricter environment policy cannot be relaxed by a client.
The operation ledger commits authorization and dispatch before effects. Restart
marks unfinished dispatches outcome_unknown, shows them when resuming history,
and never automatically replays them. Regeneration shows matching prior receipts
as “Previously executed … — run again?” and requires fresh approval. Inspect
unknown effects before approving another attempt.
Weather, web search and web_fetch(url) are available to tool-capable models by
default. The CLI shows tool progress and numbered sources after the answer;
/export retains those sources. Weather uses Open-Meteo without a key. Search
uses Keenable's public tier without a key. Set KEENABLE_API_KEY,
RAPID_MLX_TAVILY_API_KEY or RAPID_MLX_BRAVE_API_KEY in the owner's environment
to use a keyed provider. RAPID_MLX_WEB_SEARCH_PROVIDER=tavily|brave|keenable
selects explicitly; otherwise configured keyed providers precede public Keenable.
Rate limits, server errors and timeouts fail over to the next available provider.
Keys stay in memory and are never saved in chat history. Providers can throttle
or return no useful results.
Each turn carries local date, weekday, time, timezone and coarse locale beside
its user message, preserving the stable system/tool prefix. Search results keep
provider dates when available and label missing dates. Explicitly current queries
are anchored to the full local date unless they already specify a date or a
historical period. Explicit "today" searches omit known older results, retaining
unknown dates for verification; provider publication dates are not event dates.
For article summaries,
the assistant is instructed to follow the story link and cite the evidence.
Web calls are limited to four per run. All tools share a 16,000-byte model-return
allowance per run, including file and terminal output; older tool
results may be compacted for the model while original evidence remains in the
local event journal. At the limit, the runtime makes one tools-disabled answer
attempt. An empty recovery produces a visible failure message, without claiming
a verified answer.
The built-in delegate_task(task, context?, tools?) tool is available by default
inside the harness. It gives a helper a fresh history containing only its task
and supplied context. Helpers use the same local model, workspace, and approval
policy. Optional tool names narrow the parent's available tools; helpers cannot
delegate again. Up to three helpers run concurrently in the owner, using the
inference server's batching. Each helper has a 120-second deadline, six model
requests, eight tool calls, and a 12,000-token usage budget; its web/result limits
are independent of the parent's. Exhausted or timed-out helpers return an explicit
partial summary. The parent combines their summaries and sources.
The CLI shows compact nested helper progress. Child actions use the normal
approval prompt with helper attribution; Ctrl-C stops the parent and all its
helpers. Child transcripts stay out of visible branch messages but are retained
locally without reasoning and included as collapsed details in /export.
Chat stores use schema 4. Earlier experimental schemas require a new profile;
existing schema 4 profiles reopen unchanged, and incompatible stores are refused.
For offline use, set RAPID_MLX_CHAT_WEB_TOOLS=0 before starting a new profile
owner, for example RAPID_MLX_CHAT_WEB_TOOLS=0 rapid-mlx chat --harness --profile offline.
An already-running owner keeps its startup environment. Weather and search have
a 10-second total timeout. Fetch has a 20-second total timeout, allowing up to
10 seconds for Keenable before trying the direct fallback; Ctrl-C cancels an
in-flight request. Editing or regenerating a turn runs read-only tools again
for fresh information. Search returns snippets; web_fetch reads a page using Keenable, with a direct HTTP(S)
fallback that rejects private network addresses, pins validated IPs and checks
every redirect. Responses are size- and content-type-bounded; extracted page
text is capped at 8,000 UTF-8 bytes and may be shortened further to fit the
remaining tool-output allowance, with a truncation marker. Fetching needs no per-domain prompt.
MCP, custom system prompts, and Desktop integration remain outside this
experimental slice.
See the chat owner decision for lifecycle and durability details.


No comments yet.
to comment.